
Introduction: why this open release is different
I do not get excited about parameter counts. A trillion parameters sounds impressive in a headline, and it is almost useless as a buying signal on its own. What I care about is whether I can run a model, afford it, trust it with code, and tell what it did afterwards.
That is why Mistral's announcement on October 29, 2026, caught my attention. Mistral Large 4 — nicknamed "Le Chonk" — is a 1-trillion-parameter, natively multimodal flagship whose weights are being opened up. Developers and companies can download it, fine-tune it, and run it under their own policies, rather than only renting access through someone else's service.
An API is fast to start with and someone else worries about the servers. Self-hosting is slower and puts responsibility on you — but it gives you control over your data, guardrails, and costs. Mistral is betting that many developers would rather have that control. With Large 4, that bet just got a lot bigger.
One caveat runs through this whole article: the benchmark numbers below come from Mistral itself. Independent testing takes time, especially for a model this large. The honest version of this story is "Mistral claims X, and here is what X would mean if it holds up."
What Mistral Large 4 actually is
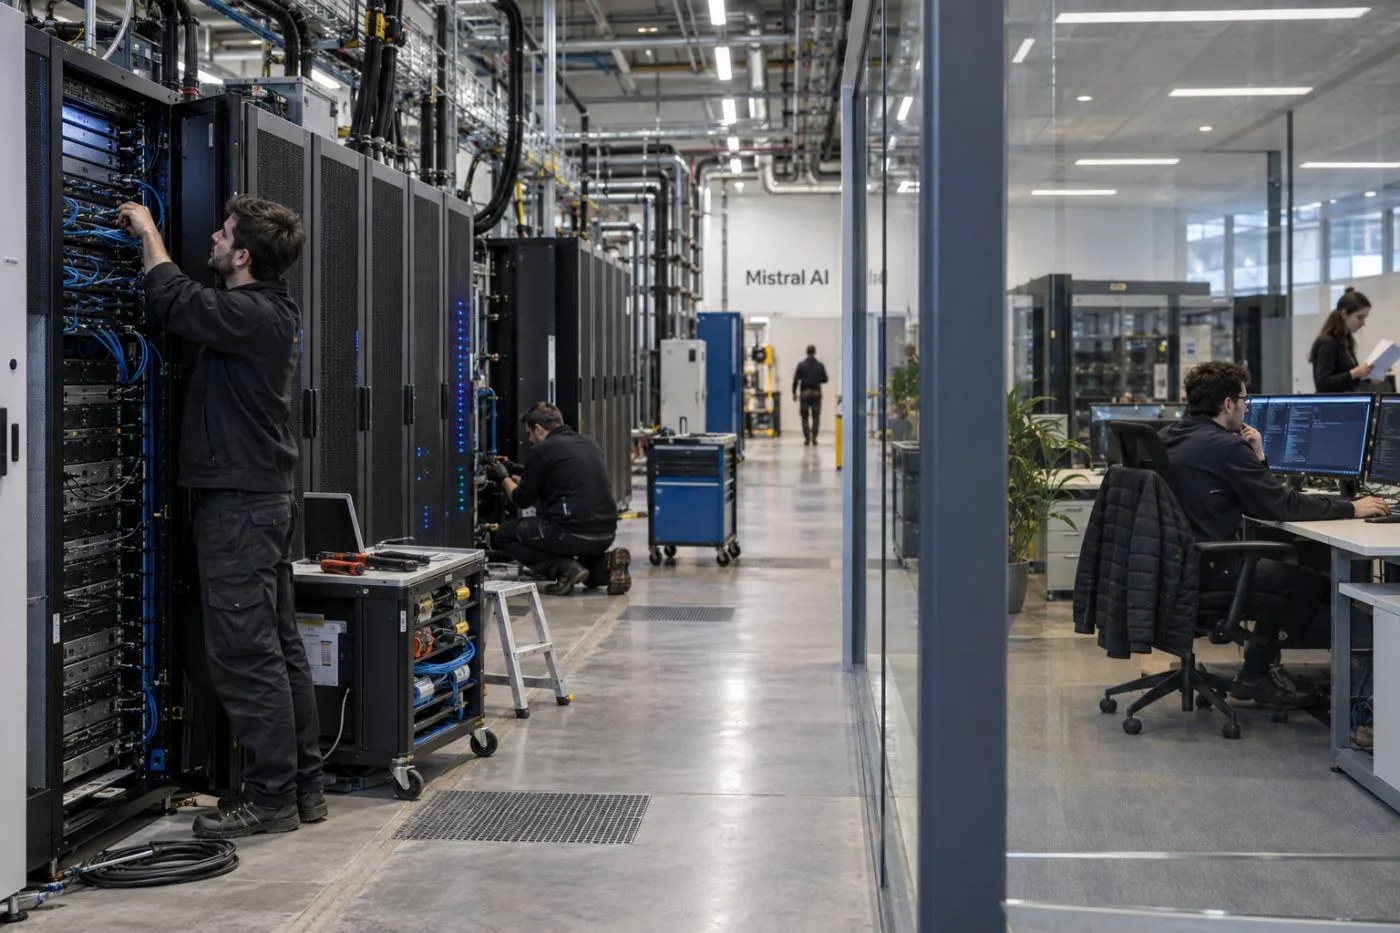
Large 4 is Mistral's flagship, and the name is doing real work. This is not a small model designed to run on a laptop. Mistral says it was trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in its own European data centres. That detail is part of Mistral's sovereignty pitch: a European frontier model, trained in Europe, that European companies and governments can run without sending data to a provider on another continent.
It is natively multimodal, meaning it was built to handle more than one kind of input from the start, rather than having vision bolted on afterwards. For my work — code, documentation, debugging — text and coding ability matter most. But multimodality helps with the workflows around that work: screenshots of a broken layout, diagrams of a system, error messages pasted as images. A model that understands those natively is more useful in a real debugging session than one that only reads text well.
The release follows a public preview on October 6, 2026. Mistral says three extra weeks of reinforcement learning after that preview drove major gains in coding and defensive cybersecurity. That is plausible and interesting, and it is exactly the kind of claim independent benchmarks exist to check.
The open-weights part is the real story
The headline is the size. The story is the licence and the distribution. Large 4 is released under a modified MIT licence: free to use, fine-tune, and commercialise, with one important exception — companies that resell the model as Model-as-a-Service need a separate commercial licence.
If you use the model inside your own product, the licence is genuinely permissive. If your business is literally reselling access to the model itself, that is where you need to talk to Mistral first. I am not a lawyer, and this is not legal advice — but if you plan to build a business around Large 4, read the licence itself, not just my summary of it.
Distribution is wide from day one: Mistral Studio, the Mistral API, OpenRouter, NVIDIA NIM containers, and Microsoft Foundry as the first cloud provider. That gives you more than one way to try the model before committing to self-hosting. Test it through an API, compare it with the models you already use, and only then decide whether running it yourself is worth the infrastructure effort.
One wrinkle: at announcement time, the main checkpoint page on Hugging Face still showed an upcoming release with an October 31 ETA, while a separate NVFP4 quantized checkpoint was already available for self-hosting. Quantized versions trade some precision for a much smaller footprint, which is how very large models become runnable outside a hyperscaler's data centre. Check the Hugging Face pages directly before planning around a specific checkpoint, and test the quantized version on your own tasks before judging the full model.
The benchmarks, with a warning label
On coding, Mistral reports 19.7% on Cognition's FrontierCode 2.0, described as the top open-weight score; 48% on the Artificial Analysis Coding Agent Index, effectively tied with GLM-5.3 while using 47% fewer tokens per task; and 41% on Terminal-Bench 4.0, up 13 points from the preview. The token-efficiency claim is the one I would watch closest. A model that reaches the same score with almost half the tokens is cheaper to run, faster to iterate with, and less likely to blow up your context window on a long task.
On security, Mistral claims 51% on the Artificial Analysis Cyber Index and an average 96.6% refusal rate on malicious cyber requests across JailbreakBench, StrongREJECT, and AgentHarm, the highest it has measured among open models. Read those together: the first is capability — can it find and fix vulnerabilities? The second is restraint — does it say no to malicious requests? A defensive tool needs both. A model that finds flaws but happily helps exploit them is a liability; one that refuses everything is useless. Mistral claims both at once, which is exactly what independent researchers will want to test hardest.
The GLM-5.3 contrast sharpens the point. A day before this release, I covered a report that Z.AI's open-weight GLM-5.3 completed 3 of 13 simulated multi-stage cyberattack scenarios and refused none of the offensive tasks given to it. Mistral is positioning Large 4 as the opposite kind of open model: capable on defence, restrained on offence, runnable under your own policies. Whether that refusal behaviour survives fine-tuning and self-hosting in the real world is the part nobody can prove on launch day.
What it costs, and what it means for web developers
API pricing starts at $0.70 per million input tokens and $2.10 per million output tokens — affordable for serious testing by a developer or small team, even if running at scale is a different conversation. The token-efficiency claim matters twice over here: comparable coding work with 47% fewer tokens means a lower effective cost per completed task than the headline price suggests.
Self-hosting is a different question. A trillion-parameter model, even quantized, is not a weekend project. It needs serious hardware, memory, and someone who knows how to operate it. Think of it as an infrastructure decision, not a download: control, data residency, and freedom from per-token pricing in exchange for hardware, maintenance, and responsibility. For a large company or security firm, that trade can be obviously worth it. For a solo developer, the API is almost certainly the sensible first step.
For WordPress and web work, I would test three uses. First, agentic coding: plugin development, theme customisation, migration scripts, and debugging plugin interactions that eat an afternoon. Second, defensive security: finding vulnerabilities, explaining them clearly, and drafting patches — with a human reviewing every change before production. I would never let any model push code to a live site unsupervised. Third, documentation: drafting docs, rewriting confusing error messages, and summarising support threads, always with a human editor checking facts. The model can speed up writing; it cannot take responsibility for what you publish.
What I would not do is rebuild my stack around Large 4 on launch week. Run it alongside your current tools, on real tasks, with real success criteria, and let the results decide whether it earns a bigger role. My own first test would be my hardest recent bug, replayed against Large 4 and my current tool with the same prompt. Benchmarks tell you what a model can do in a lab. Your own bugs tell you what it can do for you.
The honest caveats
First, every benchmark here is Mistral's own claim, not yet independently verified at scale. Second, open does not mean cheap or easy: the weights are free, but the hardware, electricity, and expertise to run them are not. Third, refusal rates on standard benchmarks do not guarantee refusal behaviour after fine-tuning or in adversarial settings — if you rely on it, test it yourself with your own red-teaming. Finally, the contrast with closed models is worth noting: in the same week, Google's Gemini 4 Carbon topped cyber benchmarks but was rolled out only to vetted cyber defenders. Developers now have a genuine choice between a closed frontier model behind vetting and an open one they can run themselves. Pick the one that fits your threat model, compliance needs, and budget.
Conclusion: a real milestone, not a magic wand
Mistral Large 4 moves the open-weight frontier in a visible, testable way: a trillion-parameter, natively multimodal model under a permissive licence, with a defensive security pitch, available through APIs, cloud providers, and self-hosting. If the coding, token-efficiency, and security claims hold up, it becomes a strong option for coding agents, defensive security work, and teams that need frontier capability without giving up data sovereignty.
But it is not a reason to throw away your current tools this week. Run it on your hardest tasks, compare it honestly, read the licence before building a business on it, and keep a human in the loop for anything touching production. Test, measure, and let the results — not the headlines — decide.
FAQ
What is Mistral Large 4 (Le Chonk)? Mistral AI's 1-trillion-parameter, natively multimodal flagship model, nicknamed "Le Chonk." Its open weights were released on October 29, 2026, after a public preview on October 6, 2026.
Is Mistral Large 4 really open source? It is open-weight under a modified MIT licence: free to use, fine-tune, and commercialise, except that companies reselling it as Model-as-a-Service need a separate commercial licence. Read the full licence before building a business around it.
How good is Large 4 at coding, according to Mistral? Mistral reports 19.7% on FrontierCode 2.0, 48% on the Artificial Analysis Coding Agent Index (tied with GLM-5.3 using 47% fewer tokens), and 41% on Terminal-Bench 4.0. These are Mistral's own figures, awaiting broad independent verification.
What does Mistral Large 4 cost? API pricing starts at $0.70 per million input tokens and $2.10 per million output tokens. Self-hosting has no per-token fee but needs serious hardware and operational effort.
Can I run Mistral Large 4 myself? In principle, yes. Weights are on Hugging Face, with an NVFP4 quantized checkpoint available at announcement time and the main checkpoint showing an October 31 ETA. Check the current pages before provisioning hardware.
Should WordPress developers switch to Large 4? Not on launch week, and not without testing. Try it alongside your current tools on real tasks and switch only if it measurably beats what you already use.
Mistral Just Opened the Weights on a Trillion-Parameter Model — Inside Large 4 (Le Chonk) and What It Means for Developers (October 2026)
On October 29, 2026, Mistral released the open weights for Mistral Large 4 — the 1-trillion-parameter, natively multimodal flagship nicknamed "Le Chonk." Here is what the model actually is, what Mistral's benchmark claims do and do not prove, how the licence works, and what I would test first before putting it anywhere near a real project.

Ahtisham Ul Haq
Lead Systems Architect & Research Editor
Looking for more WordPress & Elementor tutorials?
Explore our complete directory of 53+ web performance, theme development, and Elementor architecture guides.


